Adapter Layers vs LoRA: Efficient LLM Customization Guide
You have a massive language model. It is smart, it is capable, but it doesn't know your specific business data or speak your industry's jargon. The obvious solution? Fine-tune the whole thing. But wait-full fine-tuning of a model like GPT-3 (175 billion parameters) requires updating every single weight. That means you need massive GPU memory, days of training time, and storage space for multiple versions of the entire model if you want to serve different tasks. For most teams, this is economically and computationally impossible.
Enter Parameter-Efficient Fine-Tuning (PEFT). This isn't just a buzzword; it is a set of techniques that let you customize huge models by changing only a tiny fraction of their parameters. Two methods dominate this space: Low-Rank Adaptation (a technique that injects trainable low-rank matrices into transformer layers while freezing original weights) and Adapter Layers. If you are trying to decide which one to use, or how they actually work under the hood, you are in the right place. We will break down the math, the hardware requirements, and the real-world trade-offs so you can stop guessing and start building.
The Core Problem: Why Full Fine-Tuning Fails at Scale
Before we look at the solutions, let's look at the bottleneck. Traditional fine-tuning updates all pre-trained weights. For a 7-billion parameter model like Llama-2, that is 7 billion numbers to update and store. If you want to create a specialized version for legal contracts and another for medical diagnosis, you need two full copies of the model. Multiply that by dozens of clients or tasks, and your infrastructure costs explode.
Researchers realized something crucial around 2019-2021: when you adapt a pre-trained model to a new task, you don't need to change everything. The "intrinsic dimensionality" of the adaptation is much lower than the total number of parameters. In simpler terms, the changes needed to make the model useful for your specific job fit into a much smaller mathematical space. This insight gave birth to PEFT methods, specifically Adapter Layers, introduced in 2019, and LoRA, formally proposed by Hu et al. in June 2021.
How Adapter Layers Work
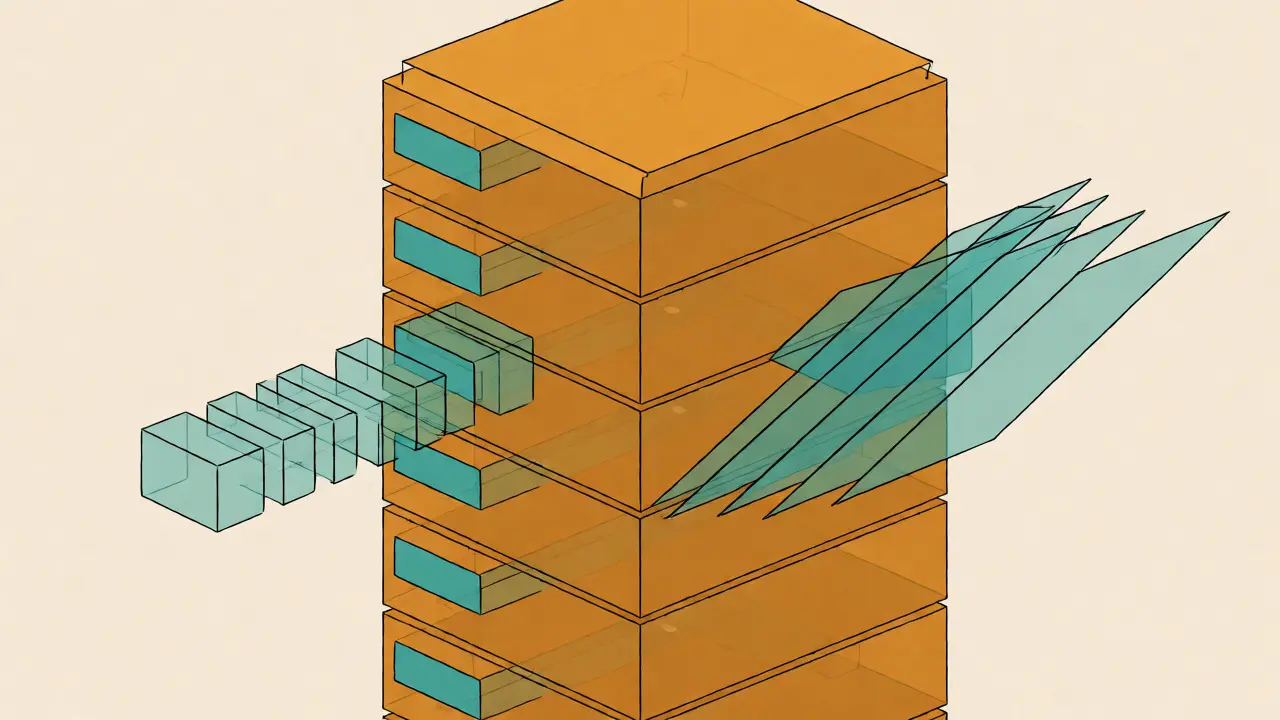
Think of adapter layers as small side-pockets attached to the main neural network. They were originally designed for BERT models but apply to modern transformers too. Instead of touching the heavy, pre-trained weights inside the transformer blocks, adapters insert small, trainable neural networks between existing layers.
Structurally, an adapter layer typically consists of three parts:
- Down-projection: A linear layer that reduces the dimensionality of the input (e.g., from 768 dimensions down to 64).
- Non-linearity: An activation function like ReLU or GELU to add complexity.
- Up-projection: A linear layer that projects the data back to the original dimensionality.
Because these layers are tiny compared to the main model, you only train them. The rest of the model stays frozen. This approach adds about 3-4% additional parameters per transformer block. While that sounds small, it introduces a sequential processing step during inference. Every token has to pass through these extra layers, which can increase latency by 15-25%. However, adapters shine in multi-task scenarios. You can swap out adapter modules without reloading the base model, making them excellent for systems that need to switch contexts frequently.
How LoRA Works
LoRA takes a different mathematical approach. Instead of adding new layers, it modifies the existing ones. Specifically, it freezes the pre-trained weight matrix $W$ and injects two trainable low-rank decomposition matrices, $A$ and $B$, alongside it. The updated weight becomes $W' = W + BA$.
Here is why this matters: if your original weight matrix is 1024x1024 (over a million parameters), you might replace it with two matrices of size 1024x8 and 8x1024. That drops the trainable parameters from ~1 million to just ~16,000. That is a reduction of over 98%. In some cases, LoRA reduces trainable parameters by up to 10,000 times compared to full fine-tuning.
The beauty of LoRA is that during inference, you can merge these low-rank matrices back into the original weights. This means there is zero added latency at prediction time. The model runs exactly as fast as the base model because the computation graph is identical. This makes LoRA the go-to choice for production environments where speed is critical.
QLoRA: Bringing Fine-Tuning to Consumer Hardware
If LoRA was a breakthrough, QLoRA was the democratization event. Introduced by Dettmers et al. in 2023, QLoRA combines LoRA with 4-bit NormalFloat (NF4) quantization. Normally, storing a 65-billion parameter model in FP16 precision requires massive VRAM. By quantizing the base model to 4-bit integers, QLoRA shrinks the memory footprint drastically. Then, it applies LoRA on top of this quantized base.
The result? You can fine-tune 30B+ parameter models on a single consumer-grade GPU, like an NVIDIA RTX 4090 with 24GB of VRAM. Before QLoRA, this required multi-GPU setups costing thousands of dollars. Independent benchmarks show that QLoRA retains about 99% of the performance of full-precision fine-tuning. For startups and individual researchers, this changed the game entirely. You no longer need a data center to customize state-of-the-art LLMs.
Comparing LoRA and Adapters: When to Use Which?
Both methods are effective, but they serve different needs. Here is a breakdown of how they stack up against each other in practical scenarios.
| Feature | LoRA | Adapter Layers |
|---|---|---|
| Inference Latency | No overhead (weights merged) | 15-25% increase (sequential layers) |
| Trainable Parameters | 0.1-0.7% of total | 3-4% of total |
| Multi-Task Switching | Requires swapping weights (slower) | Excellent (modular design) |
| Hardware Efficiency | High (especially with QLoRA) | Moderate (higher memory usage) |
| Best For | Single-task, high-speed production | Lifelong learning, many tasks |
Use LoRA if you are deploying a single specialized model and care about maximum inference speed. It is the dominant choice for enterprise applications using frameworks like Predibase’s LoRAX, which allows batching multiple adapters with minimal latency penalty. Use Adapters if you are building a system that needs to handle hundreds of distinct tasks dynamically, switching contexts on the fly without reloading the base model.
Implementation Pitfalls and Pro Tips
Even with simple libraries like Hugging Face PEFT, things can go wrong. Here are the most common issues practitioners face.
1. Rank Selection ($r$): The rank $r$ determines the capacity of the adaptation. Start with $r=8$. It works surprisingly well for most tasks. If you see underfitting (the model isn't learning the nuance), try increasing it to 16 or 32. Going above 64 rarely yields significant gains and increases overfitting risk.
2. Alpha Scaling: LoRA uses a scaling factor $ rac{\alpha}{r}$. A common heuristic is setting $ rac{\alpha}{r} = 16$. If you change $r$, adjust $ rac{\alpha}{r}$ accordingly to keep the learning dynamics stable. Ignoring this can lead to unstable training or poor convergence.
3. Layer Targeting: By default, LoRA often targets attention layers (Query and Value projections). Research suggests that targeting all linear layers (including Feed-Forward networks) can improve performance, especially for complex reasoning tasks, though it increases compute cost slightly.
4. Quantization Compatibility: If you are using QLoRA, ensure your base model supports NF4 quantization. Not all architectures do. Always verify compatibility before starting long training runs.
The Future of Efficient Customization
The market for PEFT is growing rapidly, projected to reach $8.7 billion by 2027. Innovations continue to emerge. Google Research is exploring dynamic rank adjustment, where the model decides how much capacity each layer needs during training. Meta AI is experimenting with hybrid approaches that combine LoRA with prompt tuning for better results in low-resource languages.
While adapters may hold a niche in continual learning, LoRA and its variants like QLoRA are becoming the de facto standard for general-purpose LLM customization. The fundamental principle-that model adaptation happens in a low-dimensional subspace-remains theoretically sound and practically proven. Whether you are a solo developer on a laptop or an enterprise architect, understanding these tools is no longer optional; it is essential for efficient AI development.
Does LoRA slow down inference speed?
No, not after deployment. During training, there is slight overhead, but once trained, you can merge the LoRA weights into the base model. After merging, the inference speed is identical to the original base model because the computational graph remains unchanged.
Can I use LoRA on any Large Language Model?
Yes, LoRA is architecture-agnostic and works with most Transformer-based models, including Llama, Mistral, Falcon, and GPT-J. It specifically targets linear layers within the transformer blocks, so as long as the model uses standard linear projections, LoRA can be applied.
What is the difference between LoRA and QLoRA?
QLoRA is an extension of LoRA that combines Low-Rank Adaptation with 4-bit quantization of the base model. This allows you to fine-tune much larger models (like 65B parameters) on consumer GPUs by significantly reducing memory usage, whereas standard LoRA requires more VRAM to store the full-precision base model.
Are Adapter Layers better than LoRA for multi-task learning?
Generally, yes. Adapter layers are modular and can be swapped in and out easily without modifying the base model weights. This makes them ideal for systems that need to handle many different tasks dynamically. LoRA requires swapping or merging weights, which is less flexible for rapid context switching.
How much storage does a LoRA adapter take?
A typical LoRA adapter is very small, usually between 8MB and 16MB, regardless of the size of the base model. This makes it extremely cheap to store and distribute multiple specialized versions of a large model.
- Oct, 31 2026
- Collin Pace
- 0
- Permalink
Written by Collin Pace
View all posts by: Collin Pace