LLM Total Cost of Ownership: Scaling Models Without Breaking the Bank
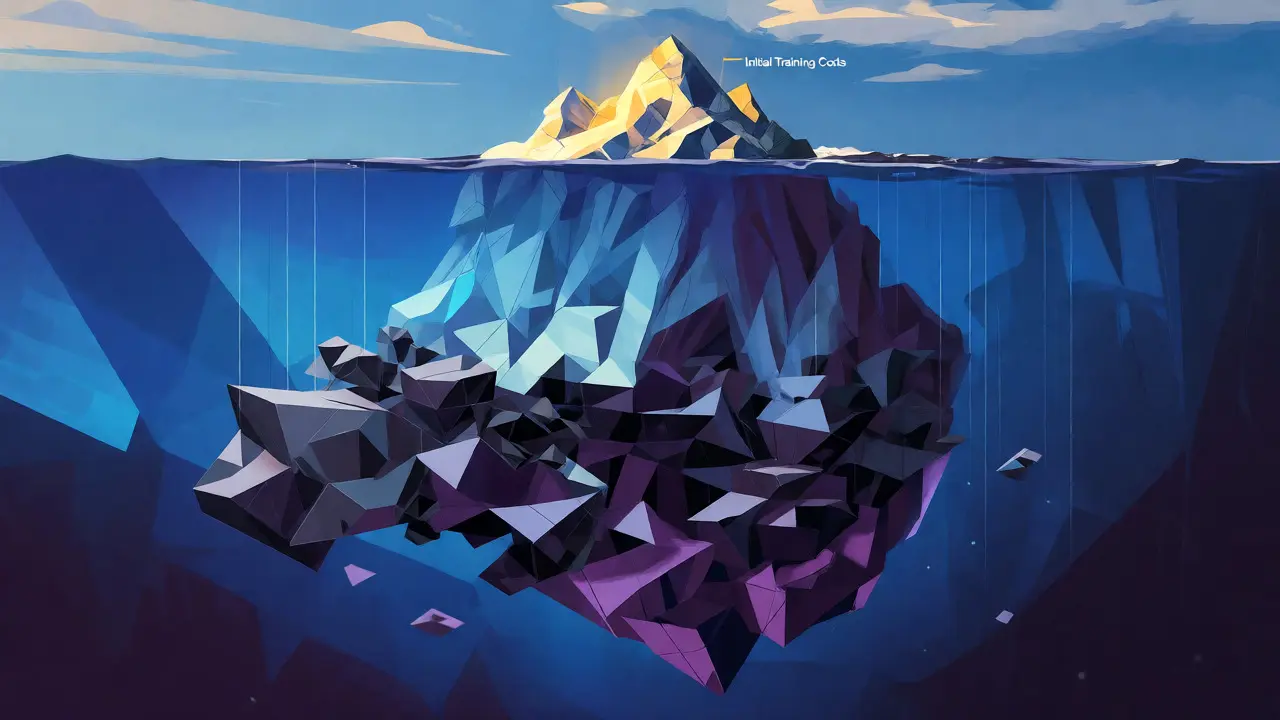
You just got a quote for training your custom Large Language Model. It looks manageable. Maybe $500k for compute, some data cleaning fees, and you’re ready to go. But here’s the kicker: that number is likely only 15% of what you’ll actually spend over the next three years. The rest? It hides in the shadows of ongoing operations, hidden maintenance, and the silent killer-data preparation.
If you are trying to scale an Large Language Model or a generative AI system, you need more than a budget sheet; you need a robust Total Cost of Ownership (TCO) model. Most companies fail here because they treat AI like software you buy once, rather than a living organism you have to feed, house, and heal continuously.
The Iceberg Problem: Why Initial Costs Lie
Let’s be real about where the money goes. Traditional IT budgets focus on acquisition. You buy the server, you pay the license, done. With LLMs, that logic breaks down. Industry analysis consistently shows that initial development and deployment represent only 15 to 25 percent of the total lifetime cost. The remaining 75 to 85 percent comes from keeping the lights on.
Think about it this way. Training a model like GPT-3 cost between $500,000 and $4.6 million depending on how you sliced the hardware. GPT-4 reportedly crossed the $100 million mark. But those one-time spikes don’t reflect the daily grind. Once your model is live, every user query costs you money. Every retraining cycle costs you money. Every hour a GPU sits idle waiting for a batch job costs you money.
Data preparation is the single largest cost component in most AI projects, often consuming 60 to 80 percent of the total effort. You aren’t just paying for GPUs; you’re paying for the army of engineers and data scientists needed to clean, label, and structure your inputs. If you ignore this line item, your TCO model is fiction.
Breaking Down the TCO Formula for LLMs
To get accurate numbers, you need to expand the standard TCO formula. It’s not just Acquisition + Operating. For AI, it’s:
- Acquisition Cost: Initial infrastructure setup, model licensing, and initial training compute.
- Operating Cost: Ongoing cloud compute, data storage, API calls, and energy consumption.
- Maintenance Cost: Model monitoring, drift detection, regular retraining, and security patching.
- Talent Cost: Salaries for ML engineers, data scientists, and the opportunity cost of diverting them from other revenue-generating projects.
- Hidden Costs: Unbudgeted contingencies, integration complexities, and currency exchange risks if your vendor bills in USD while you earn in local currency.
Ignoring talent diversion is a common mistake. When your best Python developers stop building features and start debugging why the model hallucinated yesterday, that’s a real cost. Factor it in.
Hardware vs. Cloud: The Infrastructure Decision
This is where the fork in the road gets expensive. Do you rent GPUs or buy them?
A single NVIDIA H100 GPU costs between $25,000 and $40,000. If you want a pod of 1,000 units-which is realistic for serious scaling-you’re looking at $25 to $40 million just for the metal. That doesn’t include the cooling, power, networking, or the facility to put it all in.
| Metric | Owned Hardware (CapEx) | Cloud Rental (OpEx) |
|---|---|---|
| Initial Outlay | $25M - $40M for 1,000 H100s | $0 upfront |
| Monthly Compute Cost | ~$2M (amortized) + Power/Maintenance | ~$1.50/hr per A100 equivalent (~$1,100/mo per unit) |
| Scalability | Rigid. Overprovisioning wastes cash. | Elastic. Pay for what you use. |
| Obsolescence Risk | High. Tech changes every 18 months. | Low. Provider upgrades hardware. |
For many enterprises, renting makes sense initially. Services like CUDO Compute offer A100 rentals for around $1.50 per hour. Running 1,000 GPUs for a month at roughly $2,000 per GPU-month hits $2 million. If you’re doing sporadic experiments, cloud wins. If you’re running sustained, high-volume inference with predictable loads, owning might break even after 2-3 years-but only if you manage utilization perfectly.
Training vs. Fine-Tuning: Choosing Your Path
Do you really need to train from scratch? Probably not. Full-scale training of a foundation model is reserved for tech giants. For most businesses, Fine-tuning is the viable path.
Fine-tuning a model like LLaMA 2 (70 billion parameters) typically costs tens of thousands of dollars, not millions. This approach leverages pre-existing knowledge and adapts it to your specific domain. Tools like DeepSpeed and Fully Sharded Data Parallel (FSDP) allow you to shard models across limited hardware, reducing the barrier to entry.
Compare this to the pay-per-token API model. If you use OpenAI or Google APIs, you avoid infrastructure headaches entirely. You pay per token generated. This is fantastic for startups or low-volume applications. However, if you have sustained, high-volume usage, cumulative token costs can exceed self-hosted infrastructure expenses. Run the math on your projected volume before committing to either.
The Hidden Killer: Data Preparation and Drift
We mentioned data prep earlier, but let’s drill down. In traditional software, requirements change slowly. In AI, data drifts. User behavior changes. Market conditions shift. Your model’s accuracy degrades silently.
You must budget for continuous monitoring. This isn’t just checking if the server is up. It’s evaluating output quality. Are responses becoming irrelevant? Is bias creeping in? Detecting this requires human-in-the-loop systems or automated evaluation frameworks, both of which cost money.
Retraining isn’t optional. It’s periodic maintenance. If you don’t retrain, your model becomes obsolete. Each retraining cycle incurs compute costs again. Plan for quarterly or bi-annual retraining windows in your TCO model.
Building Your 3-Year TCO Projection
Don’t look at year one. Look at year three. Here’s a practical checklist for your financial model:
- Define the Horizon: Use a 3-to-5-year window. Shorter terms miss the long-term operational burden.
- Estimate Data Costs First: Allocate 60-80% of your project effort budget to data. This includes labeling tools, storage, and engineering time.
- Model Compute Usage: Forecast tokens processed per month. Apply growth rates. Don’t assume flat usage.
- Include Talent Opportunity Cost: Calculate the salary of your ML team plus the lost productivity of product teams waiting on AI integrations.
- Add Contingency: Add 15-25% for unexpected expenses. AI projects are experimental; surprises are guaranteed.
- Account for Currency Risk: If your vendors bill in USD and you operate globally, hedge against exchange rate fluctuations.
Start with a pilot. Scale later. A focused pilot lets you refine your TCO assumptions based on real operational data, not theoretical projections. Once you have actual metrics on token usage, latency, and error rates, extrapolate to enterprise scale.
Frequently Asked Questions
Why is data preparation such a huge part of LLM TCO?
Data preparation consumes 60-80% of total project effort because raw data is rarely usable. It requires cleaning, deduplication, formatting, and labeling. High-quality input directly dictates model performance, so skimping here leads to poor outputs and costly rework later.
Is it cheaper to fine-tune or train from scratch?
Fine-tuning is significantly cheaper. Training a 70B parameter model from scratch can cost millions, while fine-tuning typically costs tens of thousands. Unless you have unique data that no existing model understands, fine-tuning offers the best ROI for most enterprises.
When does self-hosting become cheaper than API access?
Self-hosting usually becomes cost-effective when you have sustained, high-volume inference needs. If your monthly token usage is low or sporadic, APIs are cheaper due to zero upfront infrastructure costs. Calculate your break-even point by comparing cumulative API fees against amortized hardware and operational costs.
What are "hidden costs" in LLM deployment?
Hidden costs include unbudgeted contingencies, talent diversion (opportunity cost of moving staff to AI tasks), integration complexity with legacy systems, and currency exchange risks for international vendors. These often add 15-25% to the final bill if not accounted for early.
How often do I need to retrain my LLM?
It depends on your use case, but most organizations retrain quarterly or bi-annually. If your domain changes rapidly (e.g., finance or news), you may need weekly updates. Monitor for "drift," where model accuracy declines as real-world data diverges from training data.
- Oct, 2 2026
- Collin Pace
- 0
- Permalink
- Tags:
- LLM TCO
- scaling large language models
- AI infrastructure costs
- LLM training expenses
- model inference pricing
Written by Collin Pace
View all posts by: Collin Pace